Bringing up a cluster: the first 72 hours
Between the last rack landing and the first job running, there’s a checklist. Here’s what’s on it, and why we don’t skip steps.
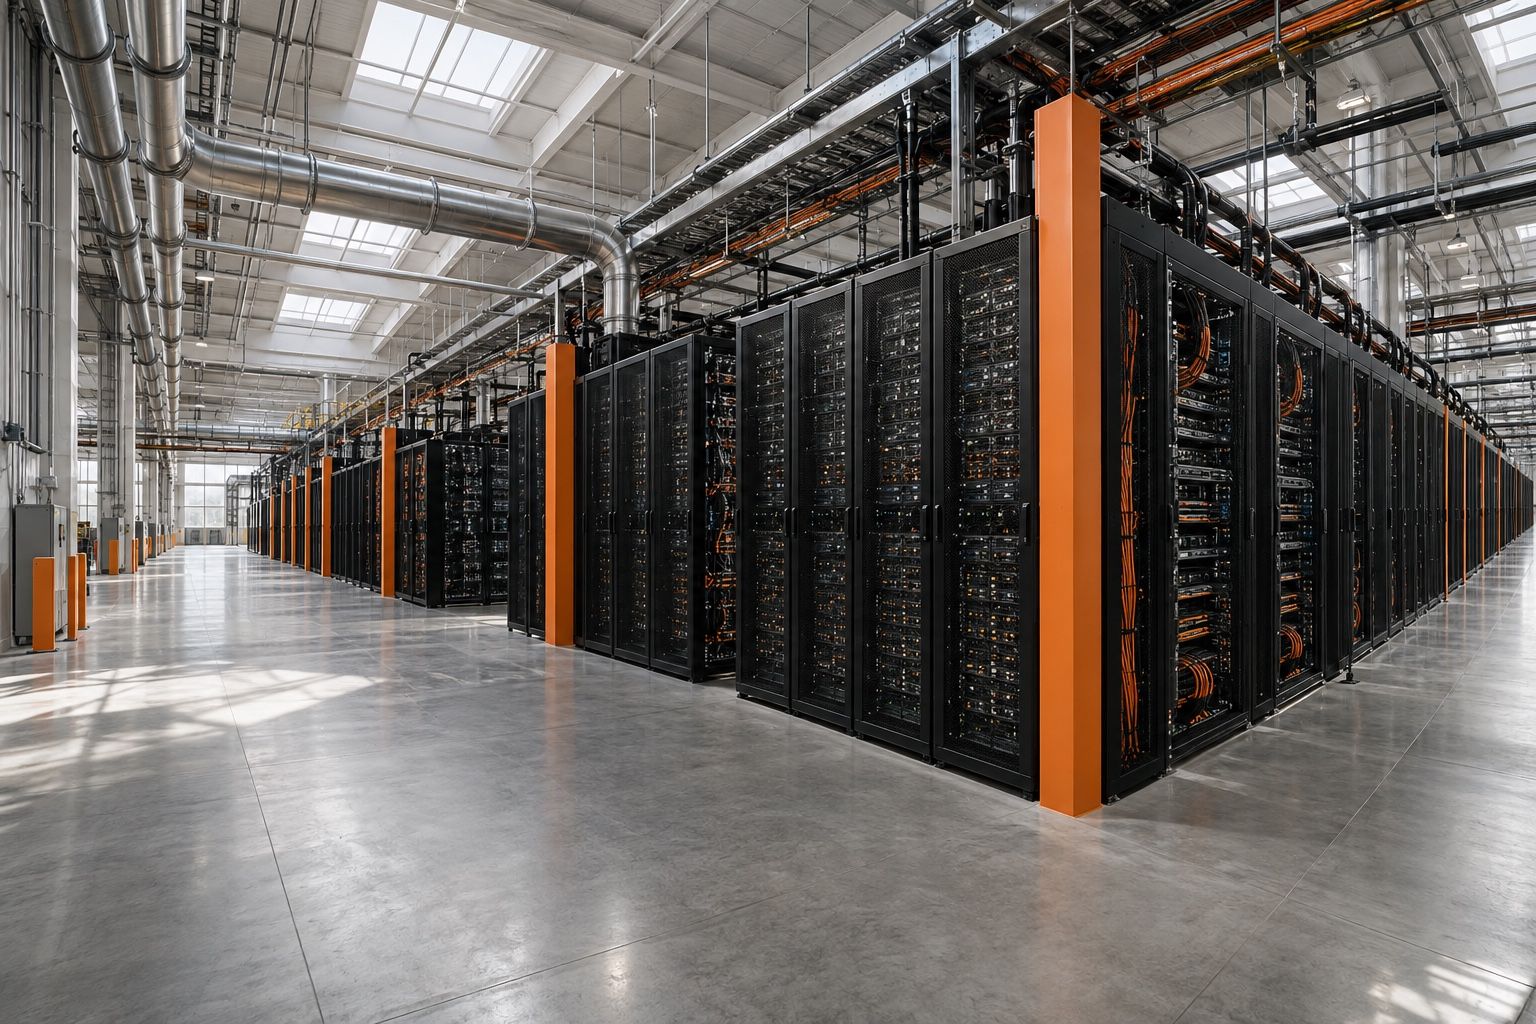
When a cluster’s racks are in place and powered, it’s tempting to call it done. It isn’t. The first few days decide whether the cluster behaves like one machine for the rest of its life.
- Power and cooling under load. Racks are brought up gradually while we watch temperatures, flow and power draw against the design.
- Firmware, everywhere. GPUs, network cards, switches and controllers are brought to one known set of versions before anything else runs.
- The fabric. Every link in the high-speed network is tested. A single bad cable can slow a whole training job.
- Burn-in. Sustained stress tests find the parts that fail early, while they’re cheap to replace.
- Handover. Only then does the cluster change hands, with the results of every test.
Seventy-two hours is a rule of thumb, not a promise; larger clusters take longer. The point is the order. Nothing reaches a customer that we haven’t run ourselves first.